What aletheia-mem gives you, and what it does not
Aletheia (npm package aletheia-mem) is a free, local memory and rules hub for AI coding tools. This post lists what it gives you, with the numbers behind each claim, and then lists what it does not give you, because the second list matters as much as the first.
The problem
Every coding agent forgets between sessions, and each one remembers differently. You explain the repository, the deploy rule and the odd naming convention on Monday, and on Tuesday the agent asks again. Switch from one tool to another and the memory does not follow you. Aletheia keeps the memory and the rules once, on your machine, and lets each tool read them in the format it already understands.
Benefit 1: one store that many tools read
One SQLite file is read over MCP (standard input and HTTP), a REST API and a command line. Thirteen MCP tools cover search, timeline, full text by id, saving a memory, rules and a work-state list. Automatic capture through hooks is built for six tools and exercised end to end against recorded payloads. What has run on a real install is narrower, and the limits section below says exactly how.
Benefit 2: private by default
- The server binds to loopback (
127.0.0.1). A different bind turns on a login and prints a warning. - There is no account and no telemetry. The default model provider is
none, so extraction is rule-based and makes no network call. - On POSIX systems the data directory has mode 0700, and the database, spool and key files have mode 0600. A few other files are looser (
alerts.dbis 0644 and the erasure export is 0664), and the 0700 directory keeps other users out. - Hooks remove secrets and
<private>blocks before anything is stored, and a project can be excluded withALETHEIA_EXCLUDED_PROJECTS. aletheia erasedeletes on purpose and writes a signed receipt. The receipt proves it was not edited, not that the data is gone from disk: the pre-erase export keeps the erased text, Aletheia does not runVACUUM, and freed SQLite pages are not overwritten at once.
Nothing leaves your machine unless you start it: a model provider you configure, sync with a hub you run, an export you share, an alert webhook, or the one-time download of the optional embedding model. Two honest cautions: redaction is pattern based, so it is not complete, and the database is plain SQLite with no encryption at rest, so use disk encryption if you need it.
Benefit 3: rules written once
A rule is a standing instruction for every tool. You write it once, and a preview-first command writes it into each tool’s own file: CLAUDE.md, AGENTS.md, GEMINI.md, Cursor and Windsurf rules, Copilot and Aider files. Those writers were tested in temporary folders. No real tool has read a rules file that Aletheia wrote, and the Copilot and Aider writers have not been verified.
Benefit 4: memory you can read, correct and take away
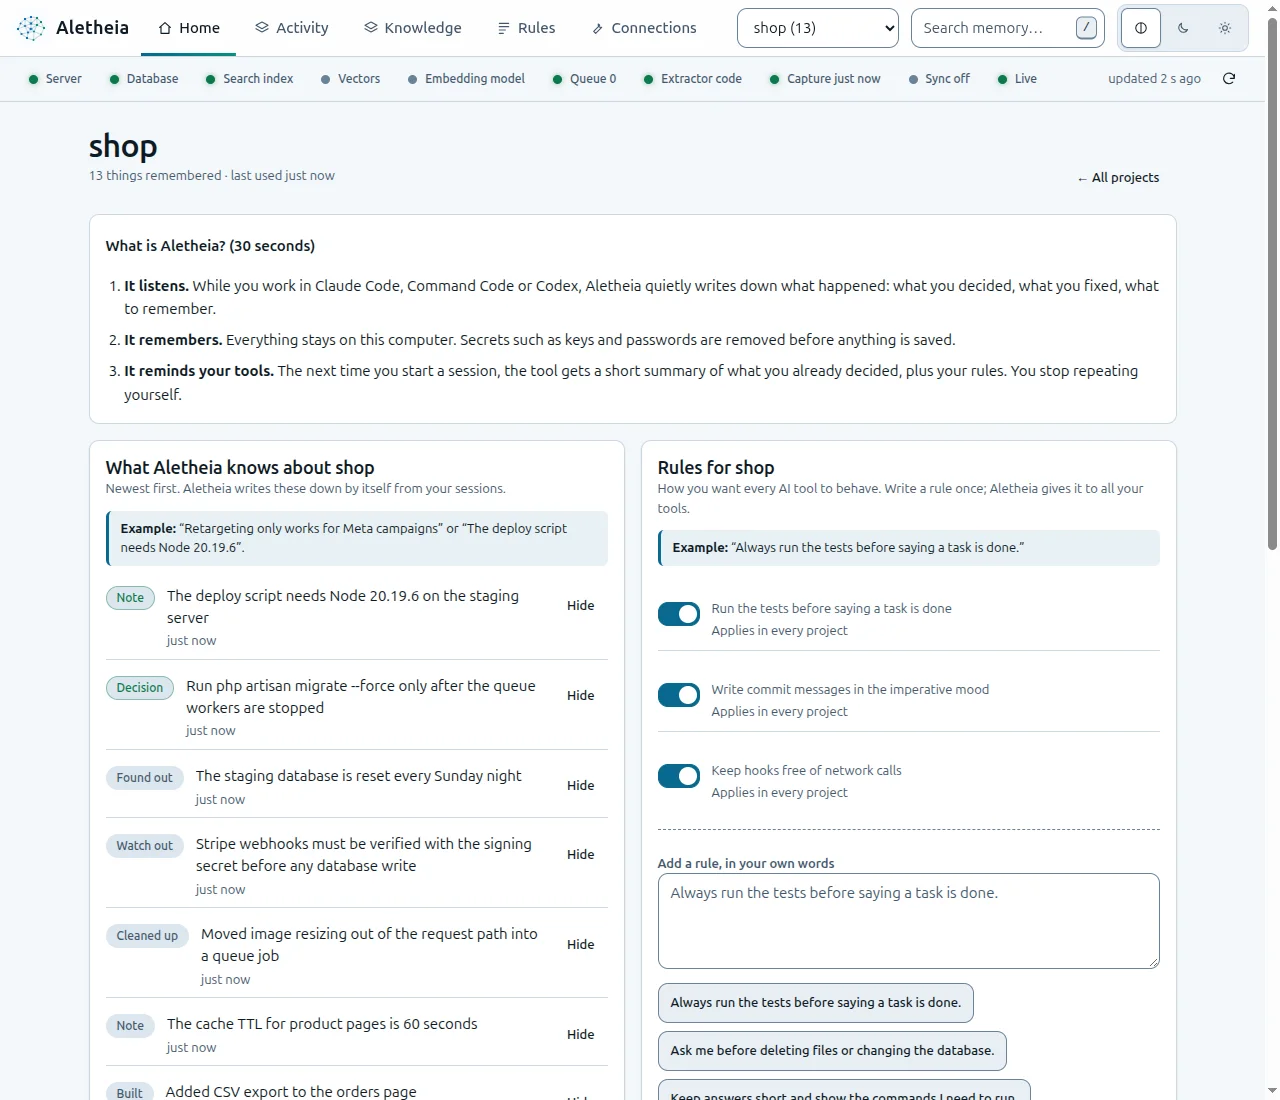
The Knowledge tab lets you search, edit, pin, hide and export. Dismiss hides a memory without deleting it, restore brings it back, and facts keep their history, so a query can ask what was true on a given date. If a note is wrong after a rewrite, you remove it from every future session in one click.
Benefit 5: a small, predictable start for each session
The session-start block is an index with one line per memory, cut at 6,000 characters. An agent that needs more calls search, timeline and get_observations. Aletheia estimates the cost in tokens as characters divided by four and says so on the last line of the block. The estimate is not a saving claim: in a tiny demo store the block was larger than the text of the memories it listed (about 194 tokens against about 132), and a real saving needs memories with long narratives.
Benefit 6: retrieval that is measured, with a published method
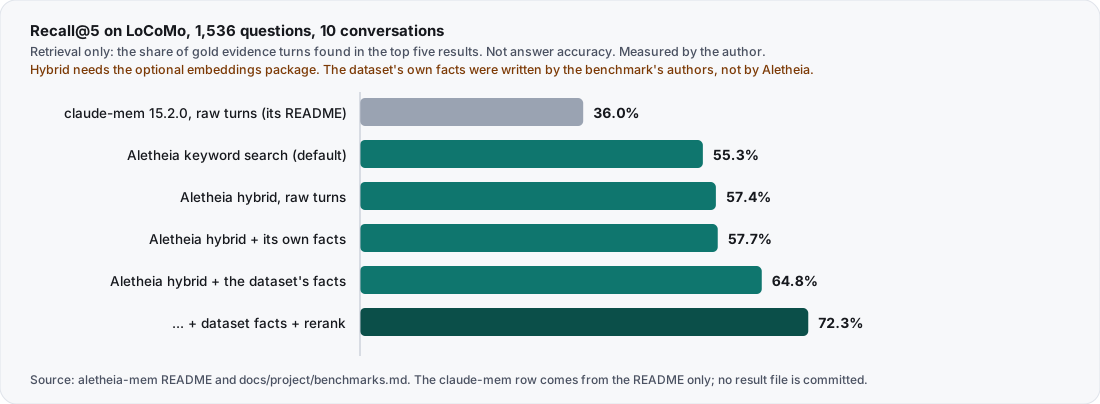
I measured retrieval on LoCoMo: the questions of categories 1 to 4 that have gold evidence, 1,536 questions over 10 conversations. Recall@5 is the share of a question’s gold evidence turns found in the top five results, averaged over questions. It is retrieval only. Every number below was measured by me, with the commands in docs/project/benchmarks.md.
| Run | Recall@5 | MRR | ms per query |
|---|---|---|---|
| claude-mem 15.2.0, raw turns, from its README | 36.0% | 0.285 | p50 1,699 ms, p95 2,824 ms (idle, 40 queries) |
| Aletheia, raw turns, keyword search (BM25, the default) | 55.3% | 0.482 | 2.00 |
| Aletheia, raw turns, hybrid | 57.4% | 0.497 | 3.72 |
| Aletheia hybrid + its own rule-extracted facts | 57.7% | 0.492 | 4.94 |
| Aletheia hybrid + the dataset’s facts | 64.8% | 0.591 | 5.53 |
| Aletheia hybrid + the dataset’s facts + rerank | 72.3% | 0.680 | 646.19 |
Read it carefully.
- Compare the claude-mem row with the raw-turns rows only. They are the only rows where both systems store the same raw text.
- The claude-mem row has no result file. It comes from the README of the project. The raw output of that run is not committed and its date is not recorded. It used claude-mem 15.2.0, saving each turn through claude-mem’s save endpoint, and newer releases exist that I did not test.
- The speed columns are not like for like. Aletheia’s figure is the mean time of an in-process ranking call. The claude-mem figures are a median and a 95th percentile for an HTTP request to a worker. They show an order of magnitude, not a ratio.
- The hybrid rows need the optional embeddings package. The default search is keyword search, the 55.3% row.
- The rule extractor barely helps. Its row is 57.7% with a lower MRR than raw turns (0.492 against 0.497). The dataset’s own facts add 7.3 points; Aletheia’s extractor does not reproduce that gain.
- There is a known gap in the evidence. A local log of the raw-turns run, which git ignores, shows 44.7% for the hybrid search. The committed result file, which the README uses, shows 57.4%. The other logs match their files. The cause is unknown and the run has not been repeated, so 57.4% is the published figure, not a settled one.
At 50,000 synthetic rows, keyword search p95 was 32.7 ms project-scoped and 58.6 ms across all projects (Linux, bun bench/scale.mjs 50000 20000 --index tuned --queries 200 --seed 1).
What it does not give you
- Answer accuracy. Recall@5 asks whether the evidence is retrieved. It does not ask whether an answer was right. A script for it exists (
bench/accuracy.mjs), but no accuracy result from a real model is published. - Proof on every tool. Hooks have run in real sessions of Claude Code (two days of use), Command Code (one short session) and Codex CLI (one interactive session), on one machine for one user. Cursor, Gemini CLI and Windsurf are configuration written from their documentation, not tested on a real install, and no hook has run inside them or inside OpenCode.
- A tested Windows setup. Continuous integration runs the tests on Windows, but several checks are skipped there, including end-to-end install and capture, and no real tool was tried.
- Complete redaction. It misses secrets that do not look like a known pattern, such as
MY_API_KEY=..., and it does not run onPOST /v1/memoriesor the dashboard note box. - Tested team sync. Sync and remote MCP are self-hosted and were tested on loopback and temporary folders, not across two real machines.
- Stability. The project is alpha.
- Native-reviewed translations. The ten README translations are machine translated.
When it is worth using
It fits if you use more than one coding tool, want your memory in a file you can read and move, or cannot send session text to a hosted service. If one tool’s built-in memory already covers you, you may not need another layer. If you need hosted team sharing with accounts, Aletheia’s team mode is self-hosted and partial.
To try it in ten minutes in a throwaway folder, follow the how-to post for aletheia-mem.
What I checked, and what I did not
The numbers come from the README, docs/project/benchmarks.md and the result files in bench/results/2026-10-26, which I read on 2026-10-31. The commands for the Aletheia rows are public, so anyone can repeat them. The claude-mem row has no result file, only the README. The token figures come from a run of aletheia context with aletheia-mem 0.1.10 in a throwaway folder on 2026-10-30. I did not rerun the LoCoMo benchmark for this post, and I did not measure claude-mem again.
What I would do differently
- Publish an answer-accuracy result before the retrieval table. A script exists, but no result from a real model is published, and readers hear “accuracy” when they see a percentage.
- Measure both sides the same way. I mix an in-process mean and an HTTP median because that is what each run reported. I would rerun both over HTTP with one statistic, and commit the raw output, so the speed difference needs no footnote.
Sources
- Aletheia README, measured numbers and limits, fetched 2026-10-31
- Aletheia documentation, privacy and redaction, fetched 2026-10-31
- Aletheia documentation, session-start context, fetched 2026-10-31
- Aletheia benchmark results, 2026-10-26, fetched 2026-10-31
